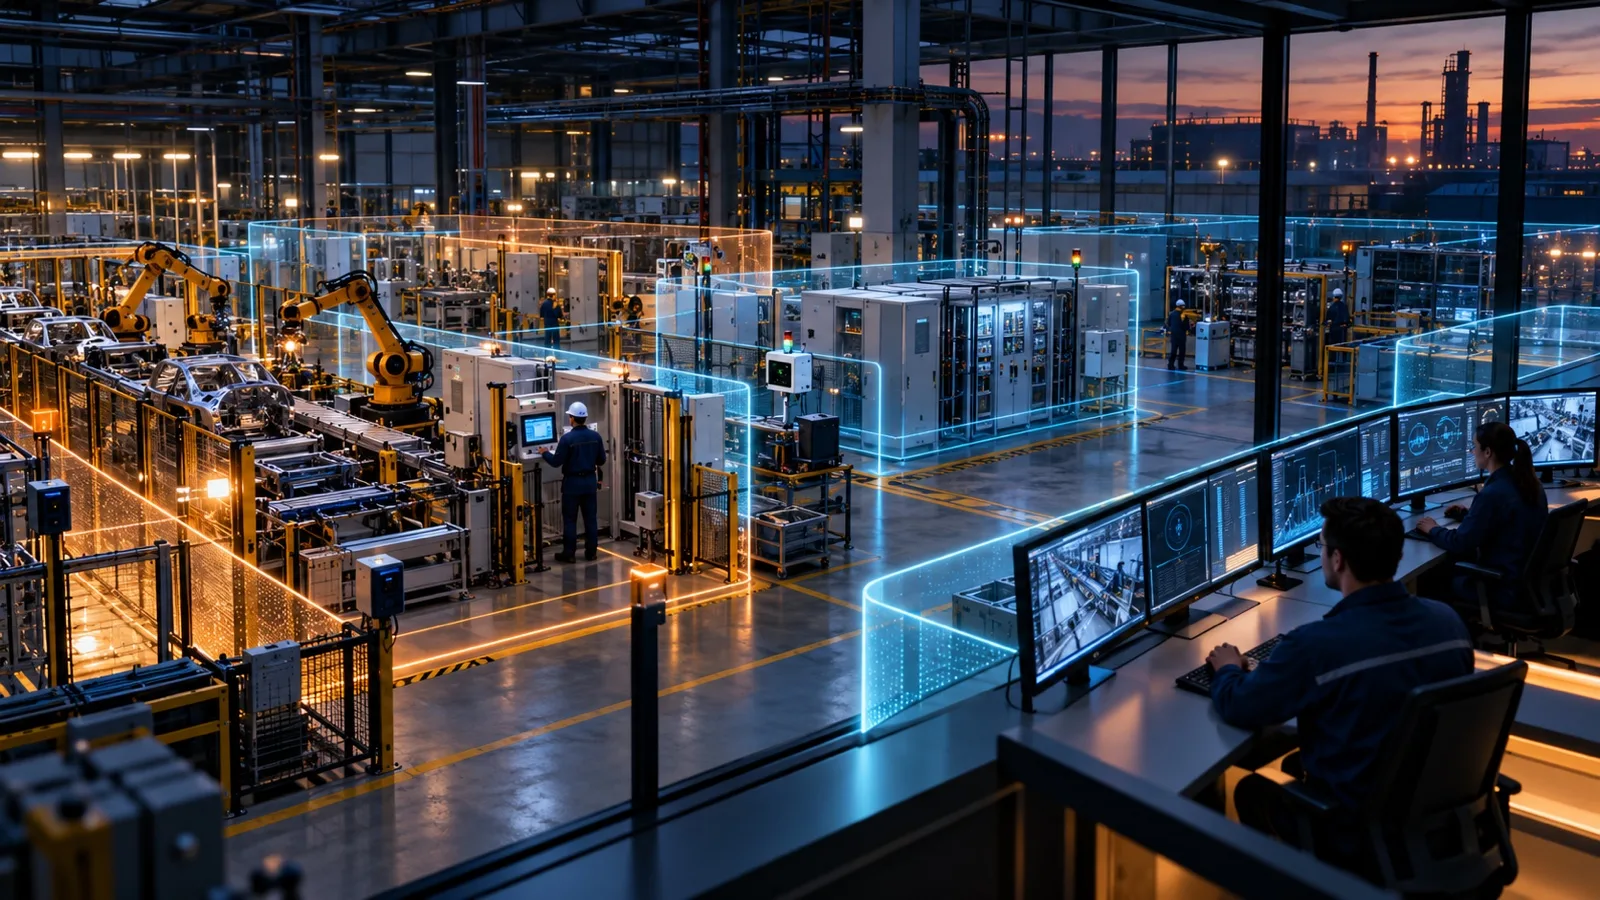
A security decision in an operational technology environment can affect a physical process. An incorrect access rule, an unplanned scan, or an inadequately tested update can cause production loss, alter equipment behavior, or create a safety risk. OT security therefore cannot be managed as a tool installation or periodic audit. Asset lifecycle, access methods, changes, recovery capability, and incident response need to operate within one model.
The program does not aim to eliminate every risk in one step. It should establish how critical processes work, detect unacceptable changes early, open access only as needed, and support safe decisions during an incident. Technical controls should be applied only after operational, maintenance, and safety requirements have been validated.
OT risk is evaluated through physical consequences
OT systems monitor or directly change the physical environment. Risk assessment therefore cannot focus only on data confidentiality. Human safety, environmental effects, product quality, equipment integrity, availability, and service continuity should be considered together. NIST SP 800-82 Rev. 3 likewise assesses OT security alongside performance, reliability, and safety requirements.
The same technical vulnerability can have different priorities on two assets. A flaw on a redundant monitoring station does not create the same physical consequence as a flaw on a controller that affects a safety function. A vulnerability score is therefore an input, not the final decision. Priority should reflect the asset's process role, reachability, dependencies, and the potential consequence of incorrect behavior.
Inventory shows asset ownership and criticality
A functional OT inventory contains more than IP addresses. Hardware model, operating system, software and firmware version, physical location, protocol, process role, responsible team, support end date, and recovery method should appear in the same record. External connections, removable media use, engineering workstations, and remote maintenance paths should also be included.
Discovery methods should match the sensitivity of the production process. Scans whose effects have not been validated should not be run directly in production. Complete the inventory through maintenance documents, existing records, and field verification. The record should be updated as a mandatory step whenever a new device, connection, or software version is commissioned.
Critical dependencies are mapped together
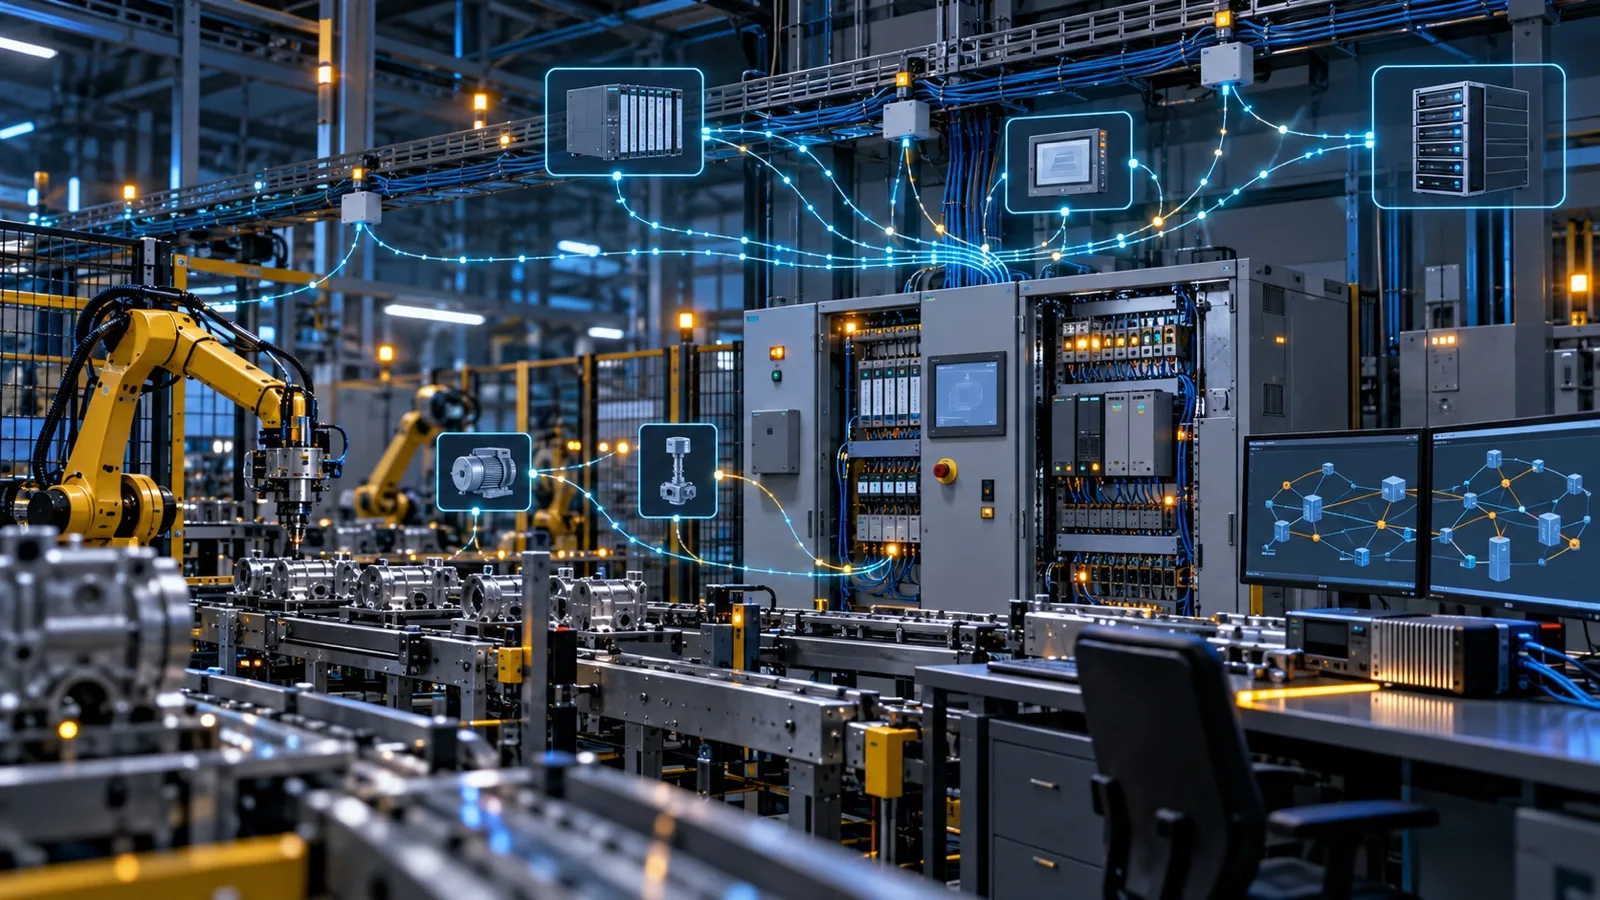
A production cell may depend on more than its controller and operator panel. An engineering workstation, historian server, time source, identity service, name resolution, license server, quality system, and remote maintenance gateway may all belong to the same recovery chain. An asset that appears in the inventory but has no known process impact cannot be prioritized correctly.
The dependency map should also show which services and physical functions are affected when an asset becomes unavailable. Loss of identity, name resolution, time, licensing, and remote maintenance services should be tested separately. Record the local capabilities required for a safe stop or restricted operation. Network segmentation is a complementary defense layer, but it does not replace knowledge of these dependencies.
Remote access is limited by purpose target and duration
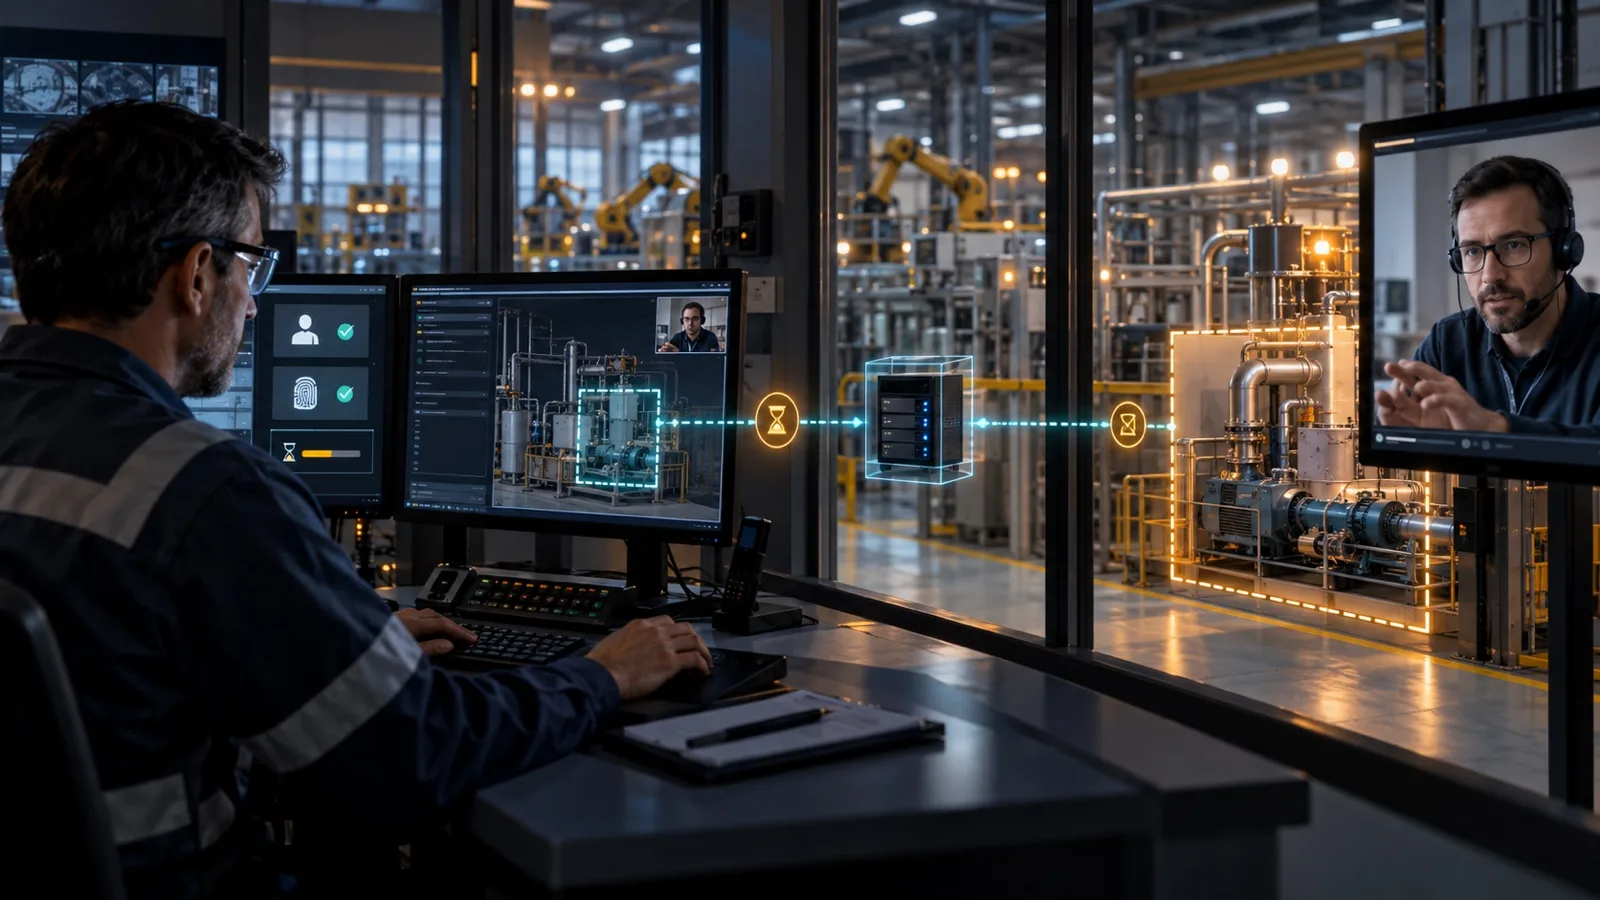
Remote maintenance should not be granted as a permanent, unrestricted network right. Link every session to a work order, individual identity, target asset, required protocol, and approved time window. Where supported, phishing-resistant multifactor authentication should be one part of the access chain, together with least privilege, a controlled access point, and session recording. Disable unused accounts and permanently open tunnels.
Emergency access should also be defined in advance. When the normal approval path is unavailable, the procedure should state who can authorize access, which privilege can remain open and for how long, and how use will be reviewed afterward. Remove temporary permission when the session ends, and record transferred files, configuration changes, and the resulting state of the target system.
Change and vulnerability management are planned around production
Not every security update can be applied to OT at the same speed or through the same method. Consider the asset's process role, exploitability of the vulnerability, existing protections, maintenance window, compatibility, and availability of a test environment separated from production. If a patch will be applied, the change plan should include rollback configuration, an offline backup, and validation steps.
Deferring an update does not remove the risk. Access restrictions, additional monitoring, reduced functionality, or temporary isolation may serve as compensating controls. Record the owner, justification, review date, and closure condition for the decision. Permanent exceptions and temporary rules without an owner turn a security gap into a lasting condition.
Monitoring gains meaning from process context
An OT monitoring program cannot produce reliable priorities without understanding normal behavior. Traffic may differ at the start of a shift, during a maintenance window, when a recipe changes, or during a planned shutdown. Passive network telemetry should be assessed together with authentication events, remote sessions, engineering workstation activity, controller program changes, and operating-mode changes.
Not every unusual packet is a high-priority event. A new communication pair, unapproved program upload, unexpected command, alarm suppression, or privileged session outside maintenance hours becomes more meaningful when assessed with its process impact. MITRE ATT&CK for ICS can help teams develop scenarios for adversary behavior and identify gaps in detection coverage. It is not, by itself, a compliance checklist or risk-scoring method.
Backup coverage should restore OT state
An OT backup contains more than server files. Controller logic, device configuration, the operator interface project, production recipes, firmware, certificates, keys, required license information, and installation dependencies should be identified by process. Backup should be linked to a change-management flow that runs before and after an approved change.
NIST SP 1339 recommends creating OT backups regularly, testing them, and reviewing them in recovery exercises. A successful copy record does not prove that the process can be restored. Where possible, separate backups from both the production environment and its identity domain, protect them against unauthorized change, and validate them through actual restore steps in an isolated environment. Measure recovery time, missing dependencies, and the safe restart sequence during an exercise.
Incident response is prepared around safe operation
An OT incident plan should define cybersecurity, process engineering, field operations, maintenance, safety, and business continuity roles in advance. Turning off a device or disconnecting it from the network may not be safe in every case. A decision to isolate equipment or move to a safe state should be based on verified effects on the physical process.
Restarting a device or immediately loading a known-good configuration before evidence is collected can erase traces of the incident. The plan should define evidence preservation, containment, safe operation, recovery order, and communication together. Manual operation is an option only when the process supports it safely and it has been tested beforehand. Exercises should go beyond tabletop scenarios to include technical restoration and controlled recommissioning in an isolated environment.
Security continues from procurement to retirement
Security begins before procurement. Acceptance criteria for a new OT product can cover default credentials, support for strong authentication, signed updates, security logging, a vulnerability disclosure process, support lifetime, secure remote maintenance, and secure erasure. CISA's Secure by Demand guidance recommends that owners and operators require these capabilities when selecting products.
During commissioning, remove or disable unnecessary default accounts. Change default credentials on accounts that cannot be removed, and use device- or user-specific identities where possible. Monitor support status and critical dependencies throughout service life. At retirement, revoke certificates, close access rights, sanitize storage securely, and close the inventory record.
Program measures should describe security outcomes
The number of installed tools does not demonstrate program effectiveness. Measures should show how much of the critical process is actually managed. Examples include the proportion of assets with verified process ownership and criticality, the proportion of remote access that uses individual accounts and session recording, successful restore-test rates for critical configurations, measured recovery time, and expired risk exceptions.
Monitoring should measure how many critical program changes and remote sessions are recorded. Incident exercises should expose actual gaps in communication, safe shutdown, manual operation, and recommissioning. The indicators should show whether uncertainty that could affect physical outcomes is decreasing over time.
Common mistakes
The first mistake is treating OT security only as a network firewall project. Network boundaries matter, but shared accounts, maintenance laptops, removable media, missing backups, and uncontrolled changes can open the same environment through other paths. The second mistake is deriving criticality solely from a technical vulnerability score. Correct prioritization requires an understanding of physical consequences.
Other mistakes include applying an untested update directly in production, leaving remote access permanently open, backing up only servers, never testing a restore, and writing the incident plan separately from field operations. If inventory, exception, and access records have no owner, the program becomes outdated over time.
Phased implementation plan
In the first phase, select one critical process and verify its supporting assets, owners, external connections, and recovery dependencies. In the second phase, remove direct internet exposure and unnecessary permanently open remote-access paths. Replace shared accounts with individual accounts where possible. Manage shared or emergency access that remains technically necessary as justified, time-limited, monitored exceptions.
In the third phase, link the approved change flow to OT backup coverage and conduct an isolated restore exercise. In the fourth phase, use passive monitoring to create alerts with process context. In the fifth phase, test an incident scenario with operations and safety teams. After findings are resolved, extend the same model to other lines and site types in a controlled manner.
Short checklist
· Are the process role, owner, version, and support status of critical assets recorded?
· Do required external connections use controlled intermediary points?
· Is remote access individual, multifactor, time-limited, and recorded?
· Does every security change include an operational test and rollback plan?
· Are controller logic, configuration, and required keys included in backup coverage?
· Is restoration tested regularly in an isolated environment?
· Do monitoring rules account for maintenance and production cycles?
· Does the incident plan explain the physical and safety effects of isolation?
· Are expired accounts, connections, and exceptions removed regularly?
Sources
· NIST SP 800-82 Rev. 3 Guide to Operational Technology Security (https://csrc.nist.gov/pubs/sp/800/82/r3/final)
· NIST SP 1339 OT Backup Quick Start Guide (https://csrc.nist.gov/pubs/sp/1339/final)
· NIST SP 1800-45 Cybersecurity for the Water and Wastewater Sector Build Architecture Operational Technology Remote Access (https://csrc.nist.gov/pubs/sp/1800/45/final)
· ISA IEC 62443 Series of Standards (https://www.isa.org/standards-and-publications/isa-standards/isa-iec-62443-series-of-standards)
· CISA Cross-Sector Cybersecurity Performance Goals (https://www.cisa.gov/cross-sector-cybersecurity-performance-goals)
· CISA Primary Mitigations to Reduce Cyber Threats to Operational Technology (https://www.cisa.gov/sites/default/files/2025-05/fact-sheet-primary-mitigations-to-reduce-cyber-threats-to-operational-technology-508c.pdf)
· CISA Secure by Demand for Operational Technology Owners and Operators (https://www.cisa.gov/sites/default/files/2025-01/joint-guide-secure-by-demand-priority-considerations-for-ot-owners-and-operators-508c.pdf)
· MITRE ATTACK for ICS (https://attack.mitre.org/matrices/ics/)
· Principles of Operational Technology Cyber Security (https://www.cyber.gov.au/sites/default/files/2024-10/principles_of_operational_technology_cyber_security.pdf)