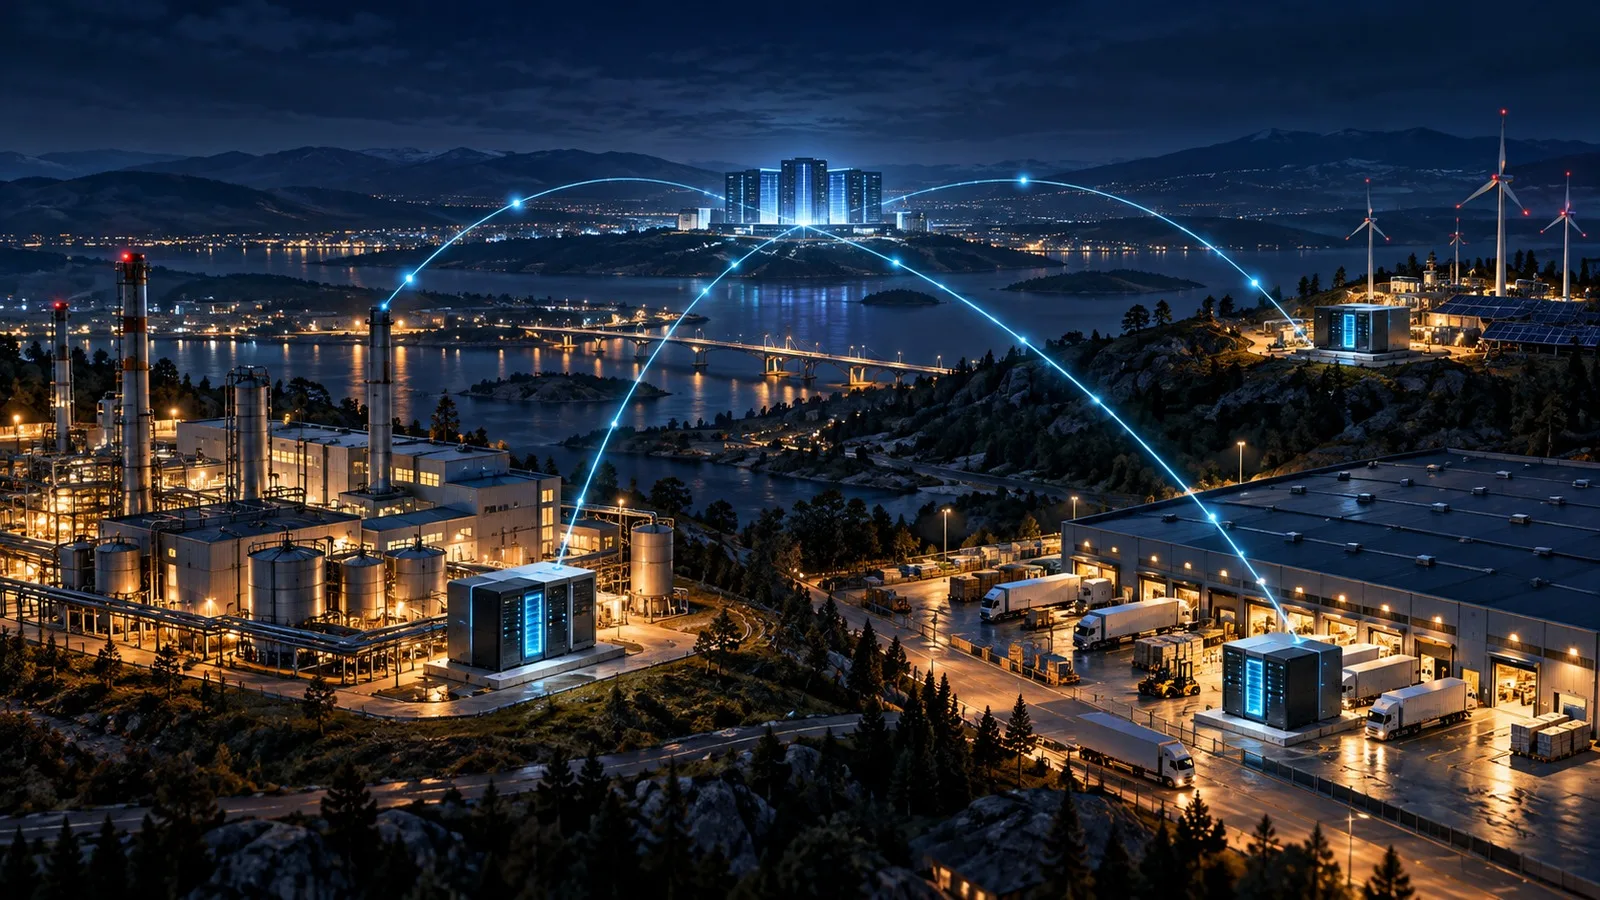
Edge computing moves processing capacity closer to where data is produced or used. Image analysis on a production line, a transaction in a store, a handheld terminal in a warehouse, or sensor data at a remote site does not have to travel to a central data center and back for every decision. This approach can reduce latency and wide-area network use, and it can allow some functions to continue locally during a connection outage. In return, a large number of small environments must be secured, updated, and monitored.
The first design question is not which server to place at the site. It is which decisions must be made locally, what latency is acceptable, which functions must survive a connection outage, and what data must synchronize with the central platform. Treating an edge node as a miniature copy of the central cloud quickly increases capacity, operating, and security costs. Every component should have a clear reason for its placement.
Workload placement follows requirements
Four main reasons justify running a function at the edge. The first is low, predictable latency. The second is maintaining local operations when connectivity is lost. The third is filtering high-volume raw data locally rather than consuming the central link. The fourth is keeping sensitive data within a defined boundary. If none of these applies, central execution is usually easier to manage.
A workload can be divided into parts. For example, real-time event detection from a camera stream may run locally, while long-term trend analysis runs centrally. The local layer retains only the short-lived data needed for a decision and sends summaries and selected events to the center. Model training, large-scale reporting, and fleet policy remain in the central layer. This creates a deliberate division of responsibility among devices, the local edge, and the central platform.
The latency budget is measured end to end
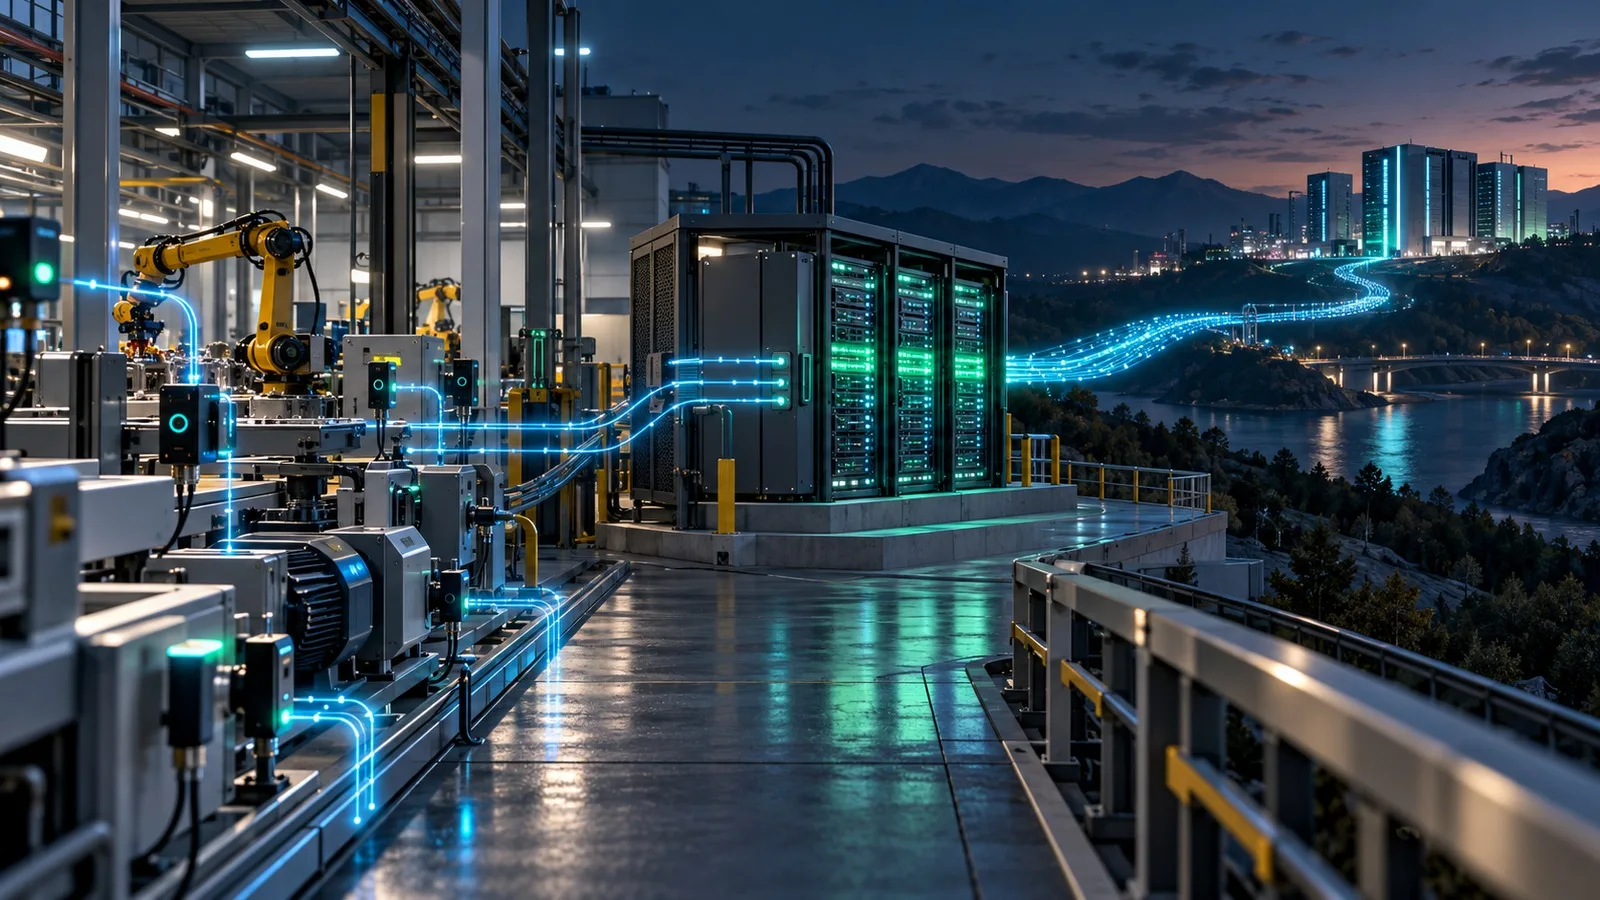
Latency consists of more than network round-trip time. The sensor generating data, a protocol gateway, queues, application processing, database access, and the response of a physical actuator all contribute to total time. Design begins with an end-to-end latency budget. Define a target and measurement point for each step. Edge placement helps only when a material part of the total delay comes from the network path.
An average alone is not enough. Production and safety scenarios should monitor 95th- and 99th-percentile latency, jitter, and packet loss. Local processor saturation, disk queues, and wireless interference can matter as much as network distance. Measurements may be misinterpreted when clocks are not synchronized. Nodes should therefore use a trusted time source and send measurements with shared identifiers to the central observability layer.
Connectivity loss is treated as a normal condition
Assuming that a remote site always has a stable, high-quality connection is fragile. The design should define in advance which functions continue in offline mode, which stop safely, and what information users see. A time-limited authorization cache may support local authentication, but indefinite offline access creates new risk. Critical commands may require additional approval or narrower permission when the connection is unavailable.
Data transfer requires a durable queue and explicit backpressure behavior. If the local disk fills while the center is unreachable, which data should the application retain, summarize, or delete? The answer should reflect business value. Sending every stored record at once when the connection returns may congest the link again. Rate control, prioritization, and gradual synchronization allow a controlled recovery.
Local state and synchronization conflicts are managed
If an edge node accepts local writes, conflicts may arise during synchronization with the central system. A simple last-write-wins rule can lose data in areas such as inventory, identity, or process settings. Define the authoritative source for each data type. The center may be the only writer for some fields, local events may be appended as immutable records for others, and some fields may require a merge based on business rules.
Unique identifiers and sequence information make duplicate deliveries safer to process. An application should not reproduce the outcome when it receives the same event more than once. Do not rely only on timestamps because clocks can drift. For long outages, validate local retention capacity, deletion policy, and synchronization time through load testing.
Central management uses a fleet model
Managing dozens or hundreds of edge nodes one by one is not sustainable. Group nodes by model, hardware class, site type, and risk level. Define desired configuration centrally; each node reports its current state and moves toward the target in a controlled manner. Updates begin with a small canary group and proceed in waves after health measurements are verified.
Update packages should be signed, their integrity checked in transit, and the node should be able to return to the previous working version if installation is interrupted. Because an edge node may remain offline for a long time, policies should state an expiry period and a minimum supported version. Inventory should include device identity, hardware, operating system, application version, certificate expiry, and last connection time.
Security also addresses physical access
Edge systems may operate outside locked data centers. The trust model should account for the possibility of physical access. Select controls such as secure boot, disk encryption, hardware-backed key storage, and tamper evidence according to risk. Default passwords and shared administrator accounts should not be used, and every node should have a unique, revocable identity.
Network access should be limited by device identity and function. From an edge node, open only the destinations and protocols required to reach the center. Separate the management interface from business application traffic. Keep certificates short-lived and test automatic renewal under outage conditions. The NIST IoT cybersecurity baseline defines capabilities such as device identity, configuration, data protection, logical access, software updates, and awareness of security state as a common starting point.
Local and central observability work together
A central dashboard cannot be the only source of information during a connection outage. The local layer should show basic health, queue depth, disk capacity, and the last successful synchronization. Critical events remain stored locally and are sent to the center in time order when connectivity returns. The central layer monitors fleet health, version distribution, offline nodes, and recurring failure patterns.
Log volume should reflect connectivity and storage budgets. Continuously sending every detail to the center can eliminate the bandwidth benefit of the edge approach. Normal operation may use summaries and sampling, while an incident can temporarily increase detail. Records containing personal or sensitive data should be minimized or masked according to local regulation and retention policy.
Capacity and lifecycle are planned
Power, cooling, physical space, and remote support may be limited at an edge location. Capacity planning should cover normal load, the queue that grows during an outage, and temporary storage needed for an update. Minimize the actions that local staff must perform after hardware failure. When a node is replaced, restore its identity and configuration securely.
Field hardware may have a longer lifecycle than a central server. Inventory should show when operating system and application support will end. Define spare parts, remote management methods, and secure erasure procedures. When a node is retired, revoke its certificate, remove its access rights, sanitize its storage securely, and close its central inventory record.
Common design mistakes
The first mistake is moving every workload to the edge without a measured latency or connectivity requirement. The second is treating an outage as an exception and failing to define offline behavior. The third is updating sites manually without central deployment, which creates version drift and security gaps.
Other mistakes include using the same identity on every node, failing to monitor local disk capacity, resolving synchronization conflicts with a last-write-wins rule, and observing systems only from the center. Ignoring physical security and failing to test update rollback can also create long outages at a site.
Phased implementation plan
In the first phase, select one use case and measure latency, data volume, outage duration, and the need for local decisions. In the second phase, map responsibilities among the device, edge, and center together with data ownership and synchronization rules. In the third phase, test offline operation, queue saturation, and connectivity recovery in a laboratory environment.
In the fourth phase, pilot identity, secure updates, rollback, and observability with a small group of sites. In the final phase, create fleet groups and deployment waves. Review capacity, certificate lifetime, version compliance, and connection quality regularly. Do not add new site types until the same controls have been verified.
Short checklist
· Is the reason for local execution and the latency budget documented for every edge workload?
· Are the functions that continue and stop safely during an outage clearly defined?
· Is the data-priority and deletion rule defined for a full local queue?
· Are duplicate messages and data conflicts handled safely during synchronization?
· Does every node have a unique identity, signed updates, and rollback capability?
· Does the central fleet view show offline nodes, versions, and certificate expiry?
Sources
· ETSI Multi-access Edge Computing (https://www.etsi.org/technical-groups/mec/)
· ETSI GS MEC 003 V4.1.1 Framework and Reference Architecture (https://www.etsi.org/deliver/etsi_gs/MEC/001_099/003/04.01.01_60/gs_mec003v040101p.pdf)
· LF Edge Edge Computing Architecture and Use Cases (https://lfedge.org/edge-computing-architecture-and-use-cases/)
· NIST Software Defined Networking Enhanced Edge Computing (https://www.nist.gov/publications/software-defined-networking-sdn-enhanced-edge-computing-network-centric-survey)
· NIST IR 8259A IoT Device Cybersecurity Capability Core Baseline (https://csrc.nist.gov/pubs/ir/8259/a/final)